Senior software engineer at EvolutionIQ
Nadeem Khan
Backend and distributed systems engineer. I build platforms where correctness and reliability are not optional: change data capture from Postgres, event-driven pipelines, and the services that run AI workloads in production.
NowAt EvolutionIQ: the event-driven pipelines that make claim documents searchable as they land, and the worker pools behind our LLM calls.
Kafka CDC from Postgres to Salesforce and the lake, as built at Crowe: 60M+ row changes a day at month-end peak. Hover a component for the guarantee it holds.
Read the CDC series (opens in a new tab)Experience
Mar 2026 to nowNew York, US
EvolutionIQ Senior Software Engineer
Re-architected an existing event-driven pattern for a CPU-bound embedding workload: Pub/Sub into Postgres-backed job queues, separate subscriber and worker pools, 100 in-flight messages as backpressure. Documents went from waiting up to 30 minutes to searchable on arrival. Replaced a deadline-bound RPC router with a worker pool scaled on queue depth, taking LLM fallbacks from about 2% to zero so the legacy path could be deleted.
Jan 2022 to Mar 2026Chicago, US
Crowe Senior Software Engineer
Architected and built the first version of real-time CDC from a Postgres ERP into Salesforce, carrying 60M+ row changes a day at month-end peaks, then re-architected it onto Kafka when a second consumer arrived. Built a control loop that projects WAL growth against the primary's 50 GB slot budget and restarts the connector or resets the slot before it is reached, cutting manual-intervention incidents by about 70 to 80%. Led the SQL execution platform and its team of about ten.
Jan 2021 to Feb 2022Boston, US
Boston University MSc Computer Science, research and teaching
Led product development for a public data-visualisation platform on US racial disparities at the Center for Antiracist Research (React, D3). Teaching assistant for MET CS 677, Data Science with Python.
Mar 2018 to Dec 2020India
Crowe Backend Team Lead
Led a team of five building a horizontally scalable microservice platform for a SaaS product on Spring, Docker and Kubernetes, with autoscaling tuned to 70% average CPU.
Live systems
All projects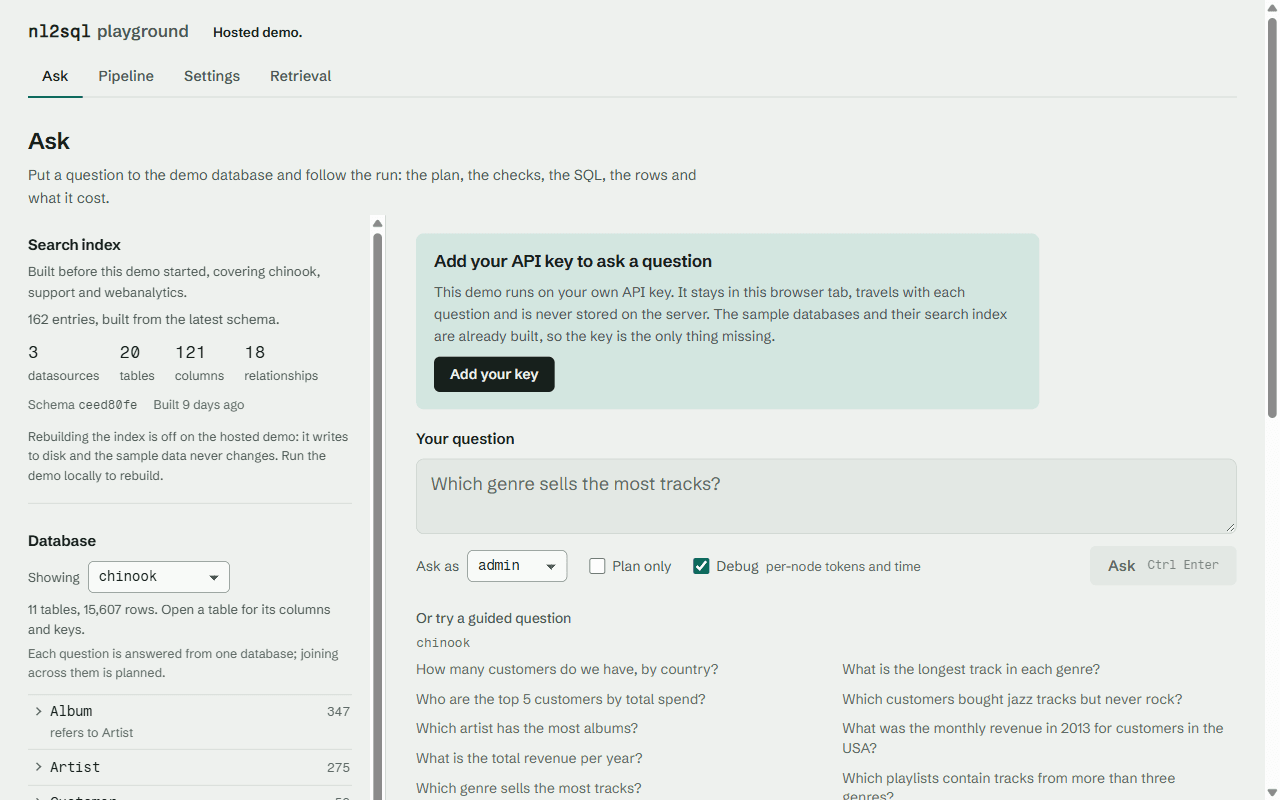
nl2sql playground
Ask your database questions in English. The model emits a typed query plan, never SQL text - validated against the real schema and the caller's role before any SQL is generated.
question → planner (typed plan, never SQL) → validator (schema, joins, role) → sqlglot → read-only executor
A plan that fails validation never becomes SQL, and a security refusal is final. On PyPI as nl2sql-engine.
Post-training
A collection of small, runnable implementations of LLM post-training and alignment methods, from RL basics to DPO, RLHF, and RLAIF.
environment → agent (Q-learning, DQN, PPO, GRPO) → policy update → tests
Each method is small enough to read in one sitting, and each has its own tests.
Decision Arena
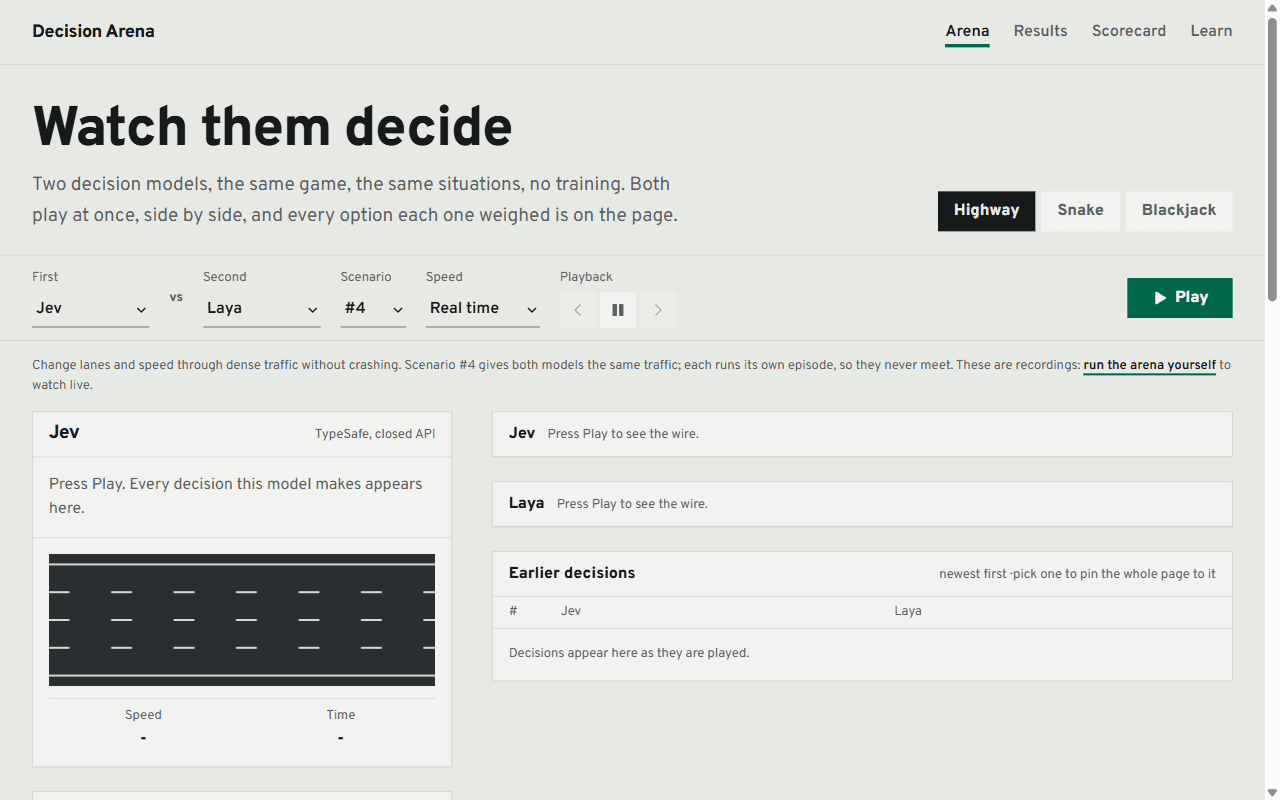
Decision Arena: TypeSafe's Jev vs open-source Laya playing highway-env, Snake and Blackjack with zero training, plus benchmarks and a Claude Code watchdog
game state → decision model (Jev or Laya) → probability per allowed action → environment step
The model can only answer with an option on the list. Includes agent-watchdog, which scores each Claude Code tool call before it runs.
RAG playground
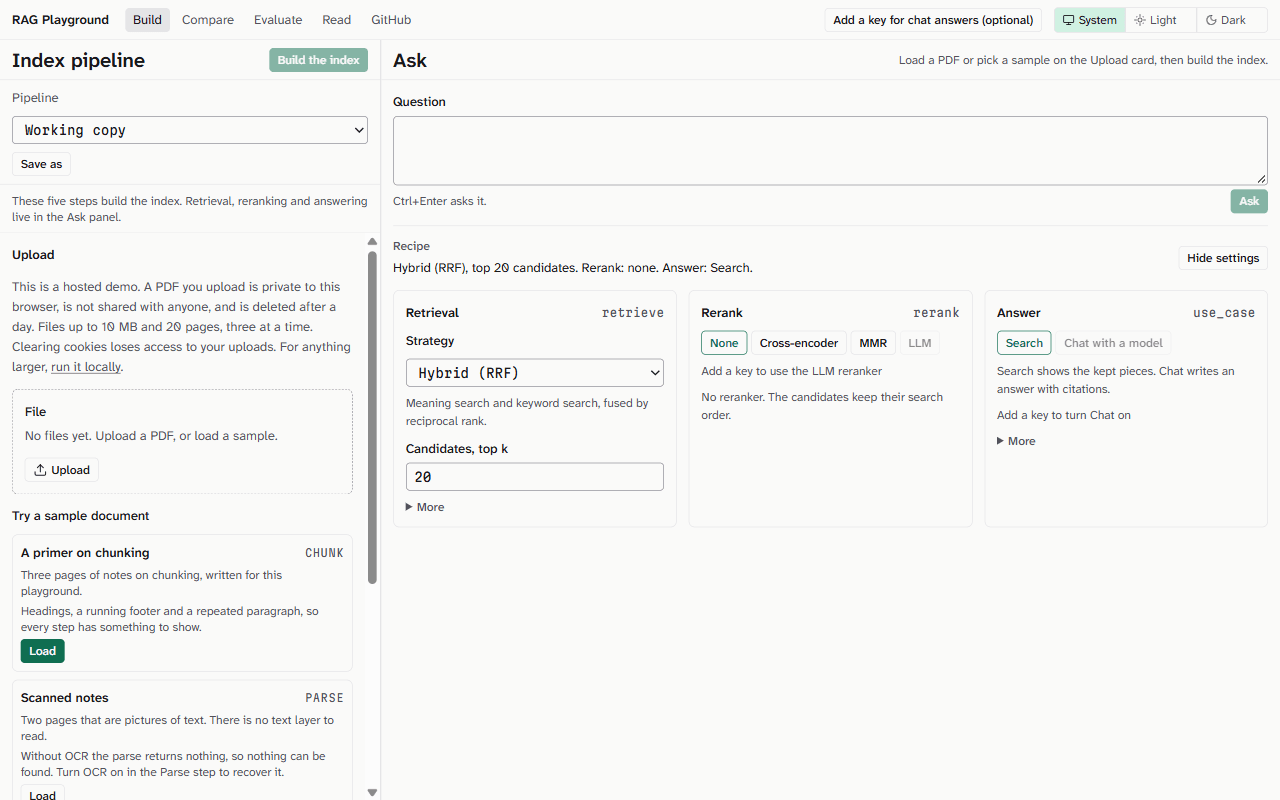
A local-first bench for learning and demonstrating RAG by experiment
PDF → parse → clean → chunk → index → retrieve (dense, keyword or hybrid) → rerank → cited answer
Every stage is swappable, and evaluation says why each miss missed.
Open source
GitHub ↗- logscribe (opens in a new tab)
AI-powered log analysis for Python logging: batch, scrub PII, and route logs to an LLM for insights.
Python, Aug 2026
- medalflow (opens in a new tab)
dbt, but in Python classes. Declare medallion (Bronze/Silver/Gold) models as Python classes; MedalFlow extracts dependencies from your SQL and compiles them into a staged execution plan.
Python, Aug 2026
Writing
All 120 postsTry
Selected
- How Kafka Really Works: Lessons from a 60M+ Events/Day Production Pipeline (opens on Medium)
Backend & Infra,
- Protecting PostgreSQL Primaries from Replication Slot Failures (opens on Medium)
Postgres Series,
- PostgreSQL Logical Replication at Scale: Database-Side Guardrails for 60M+ Change Events (opens on Medium)
Postgres Series,
- How to Stop Your NL2SQL Agents From Crashing in Production: The Worker-Pool Pattern (opens on Medium)
AI System Design,
Latest
- Parsing Documents: PDFs, Tables, Scans and Layout (opens on Medium)
AI System Design,
- Cleaning and Deduplication Before Anything Is Embedded (opens on Medium)
AI System Design,
- I Tested Jev and Laya, Two New AI Decision Models, on Games They Were Never Trained For (opens on Medium)
LLM Architectures,
- Decision Models: How Jev and Laya Decide Without Writing Text (opens on Medium)
LLM Architectures,
Tools I use
Systems
- Kafka
- Debezium
- Postgres logical replication
- Pub/Sub
- Postgres job queues (Procrastinate)
- Durable Functions
- OpenTelemetry
Data
- PostgreSQL
- SQL Server
- MySQL
- Azure Synapse
- Delta Lake
AI
- LangGraph
- RAG
- Embeddings and vector search
- LLM inference
Languages
- Python
- Java
- SQL
- TypeScript
Cloud
- Google Cloud
- Azure
- Docker